Same-base cohort / top 20 by downloads
What does fine-tuning change?
Compare derivatives of Qwen3.5-0.8B-Base against the original checkpoint: gains, regressions and cost within the same benchmark protocol.
- Selected finetunes
- 20
- Measured text systems
- 15 / 15
- Base ARC-Easy
- 70.54%
- Processing / queued
- 0 / 0
Pinned snapshot 2026-10-17T03:33:12.159677+00:00. Hub tensor totals can include duplicated tied weights. Above-1B metadata is a review flag; eligibility requires unique loaded-model parameter counts. Names and base-model tags do not establish size.
Measured comparison plots
Original base model · all benchmark results →
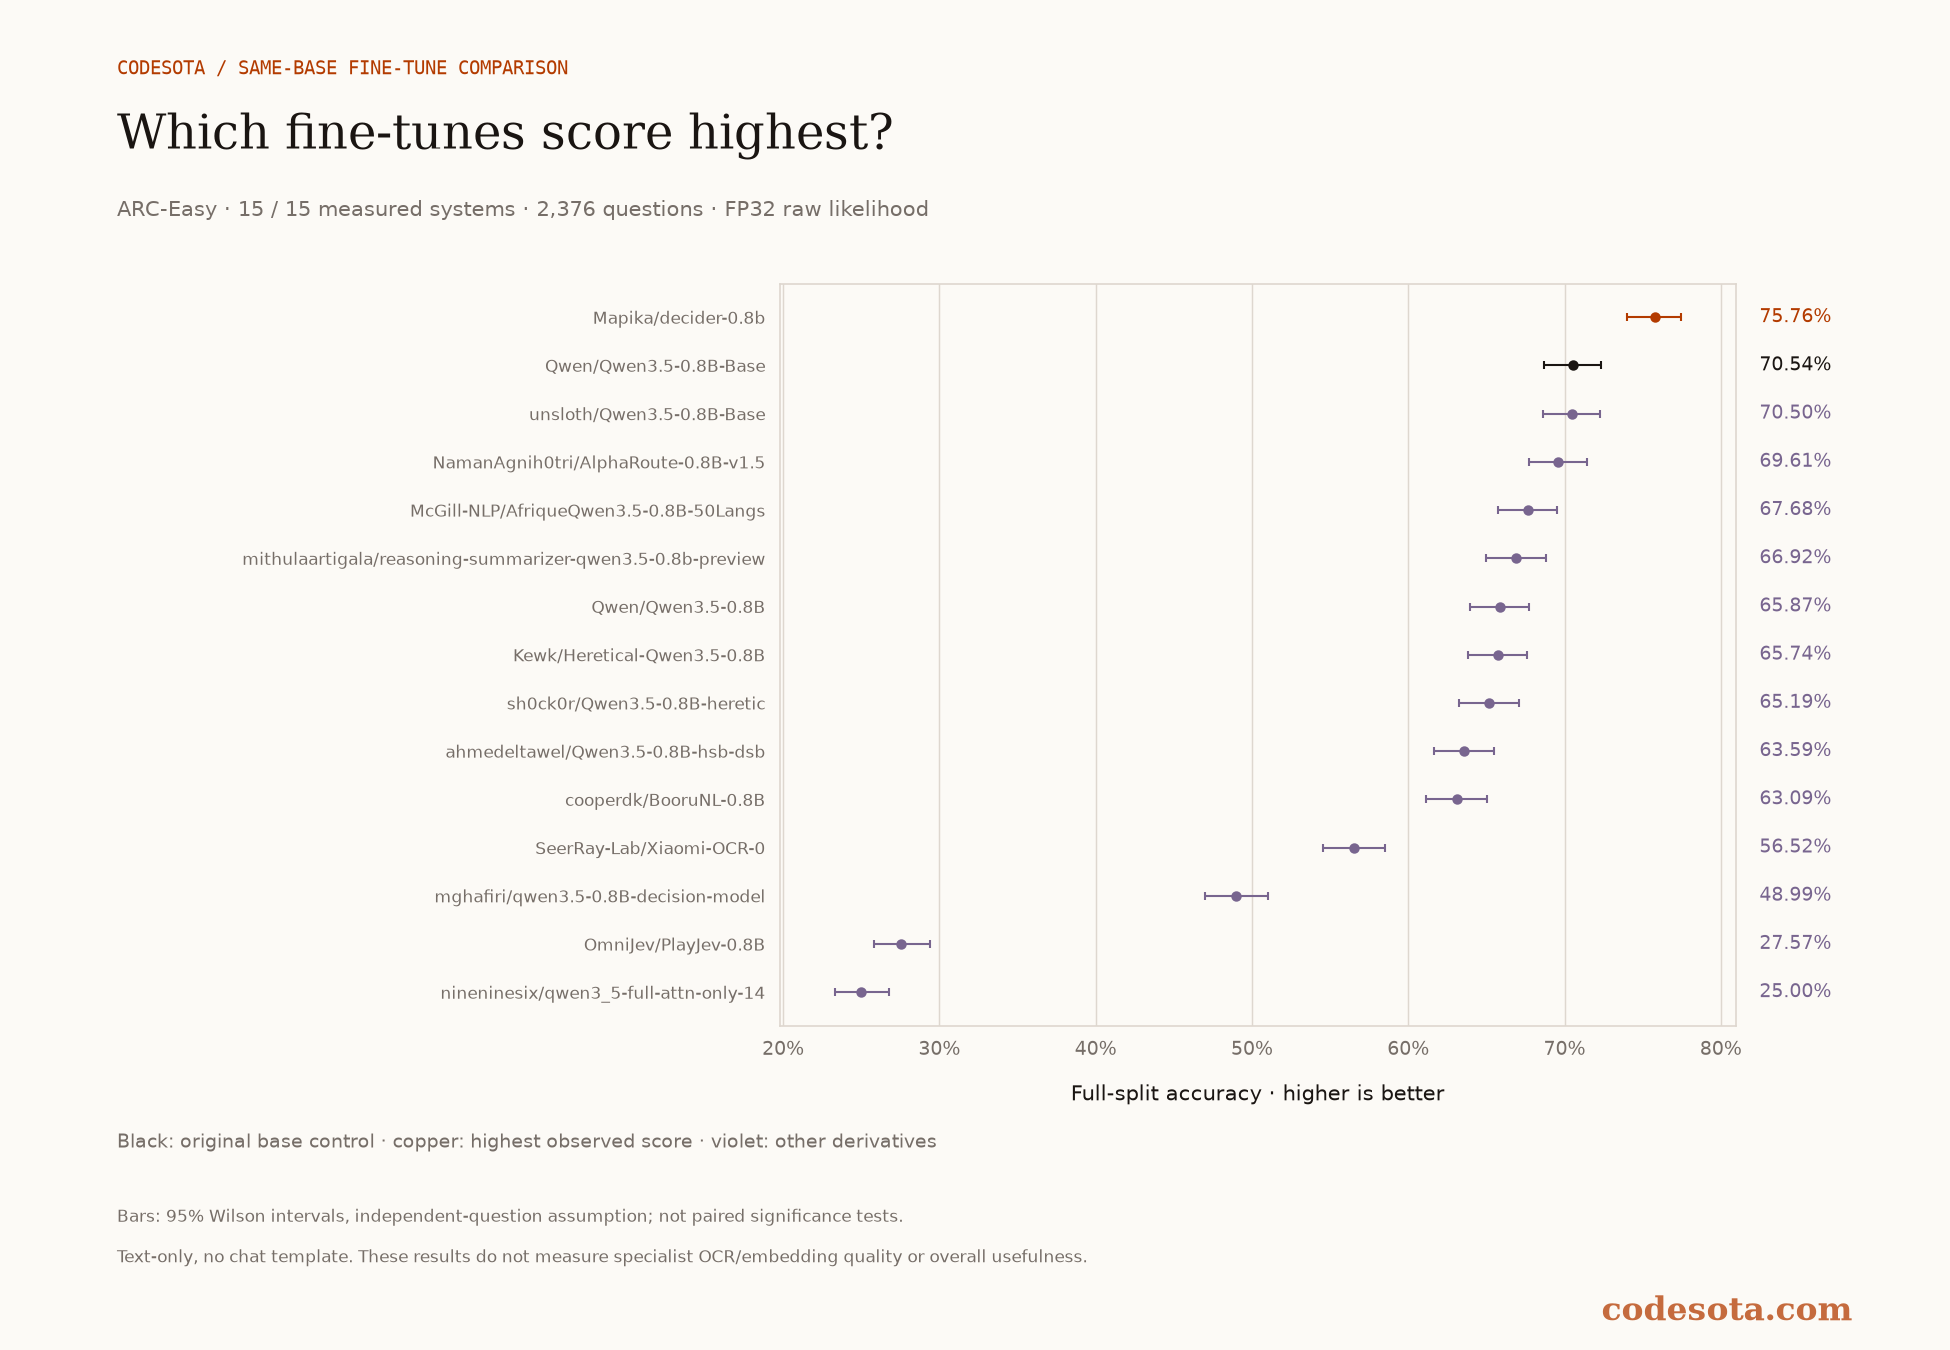
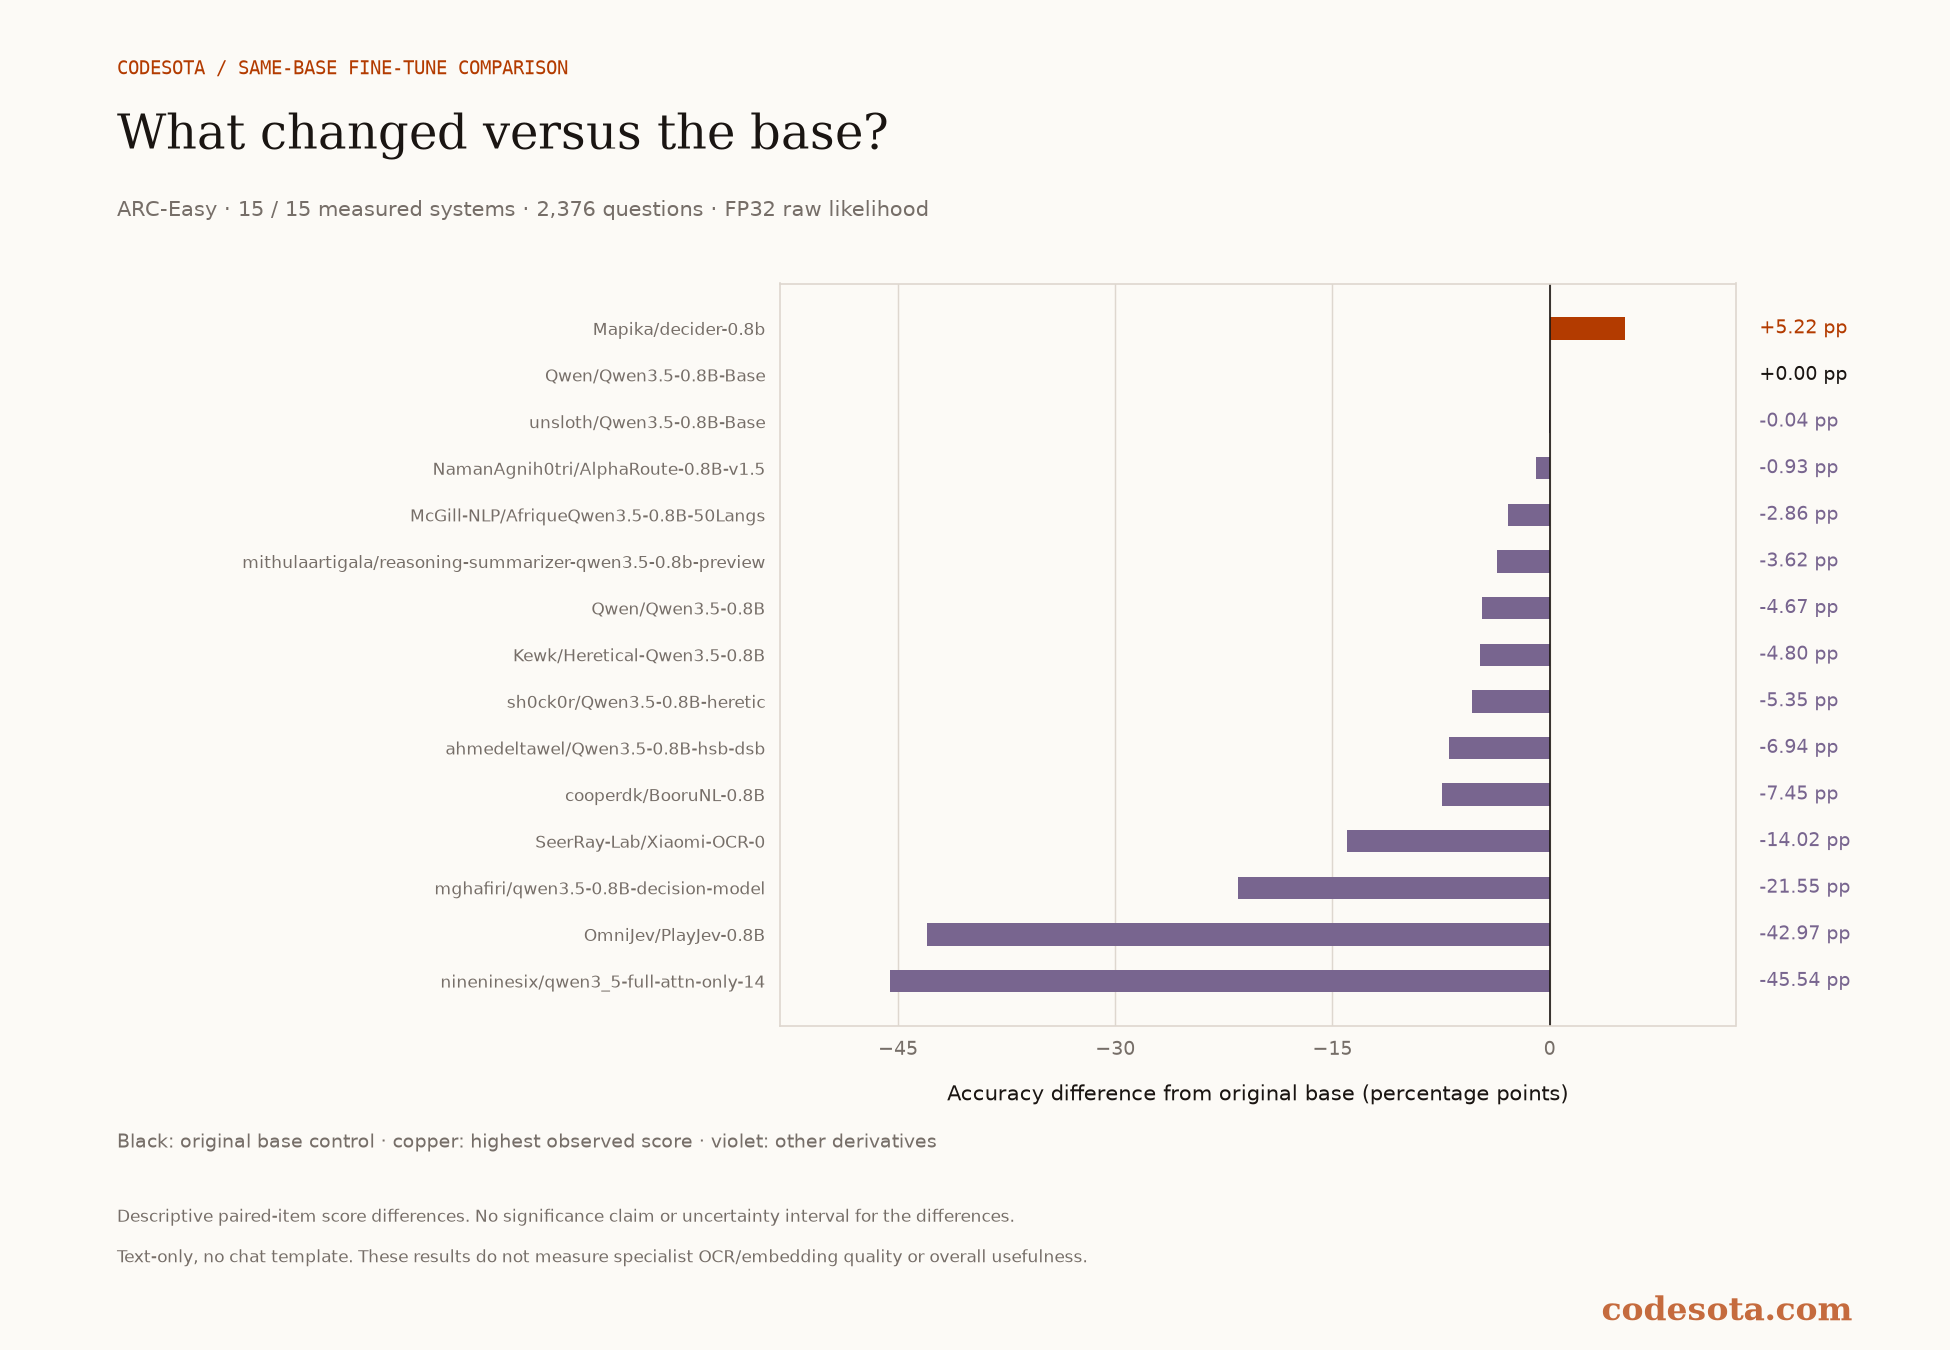
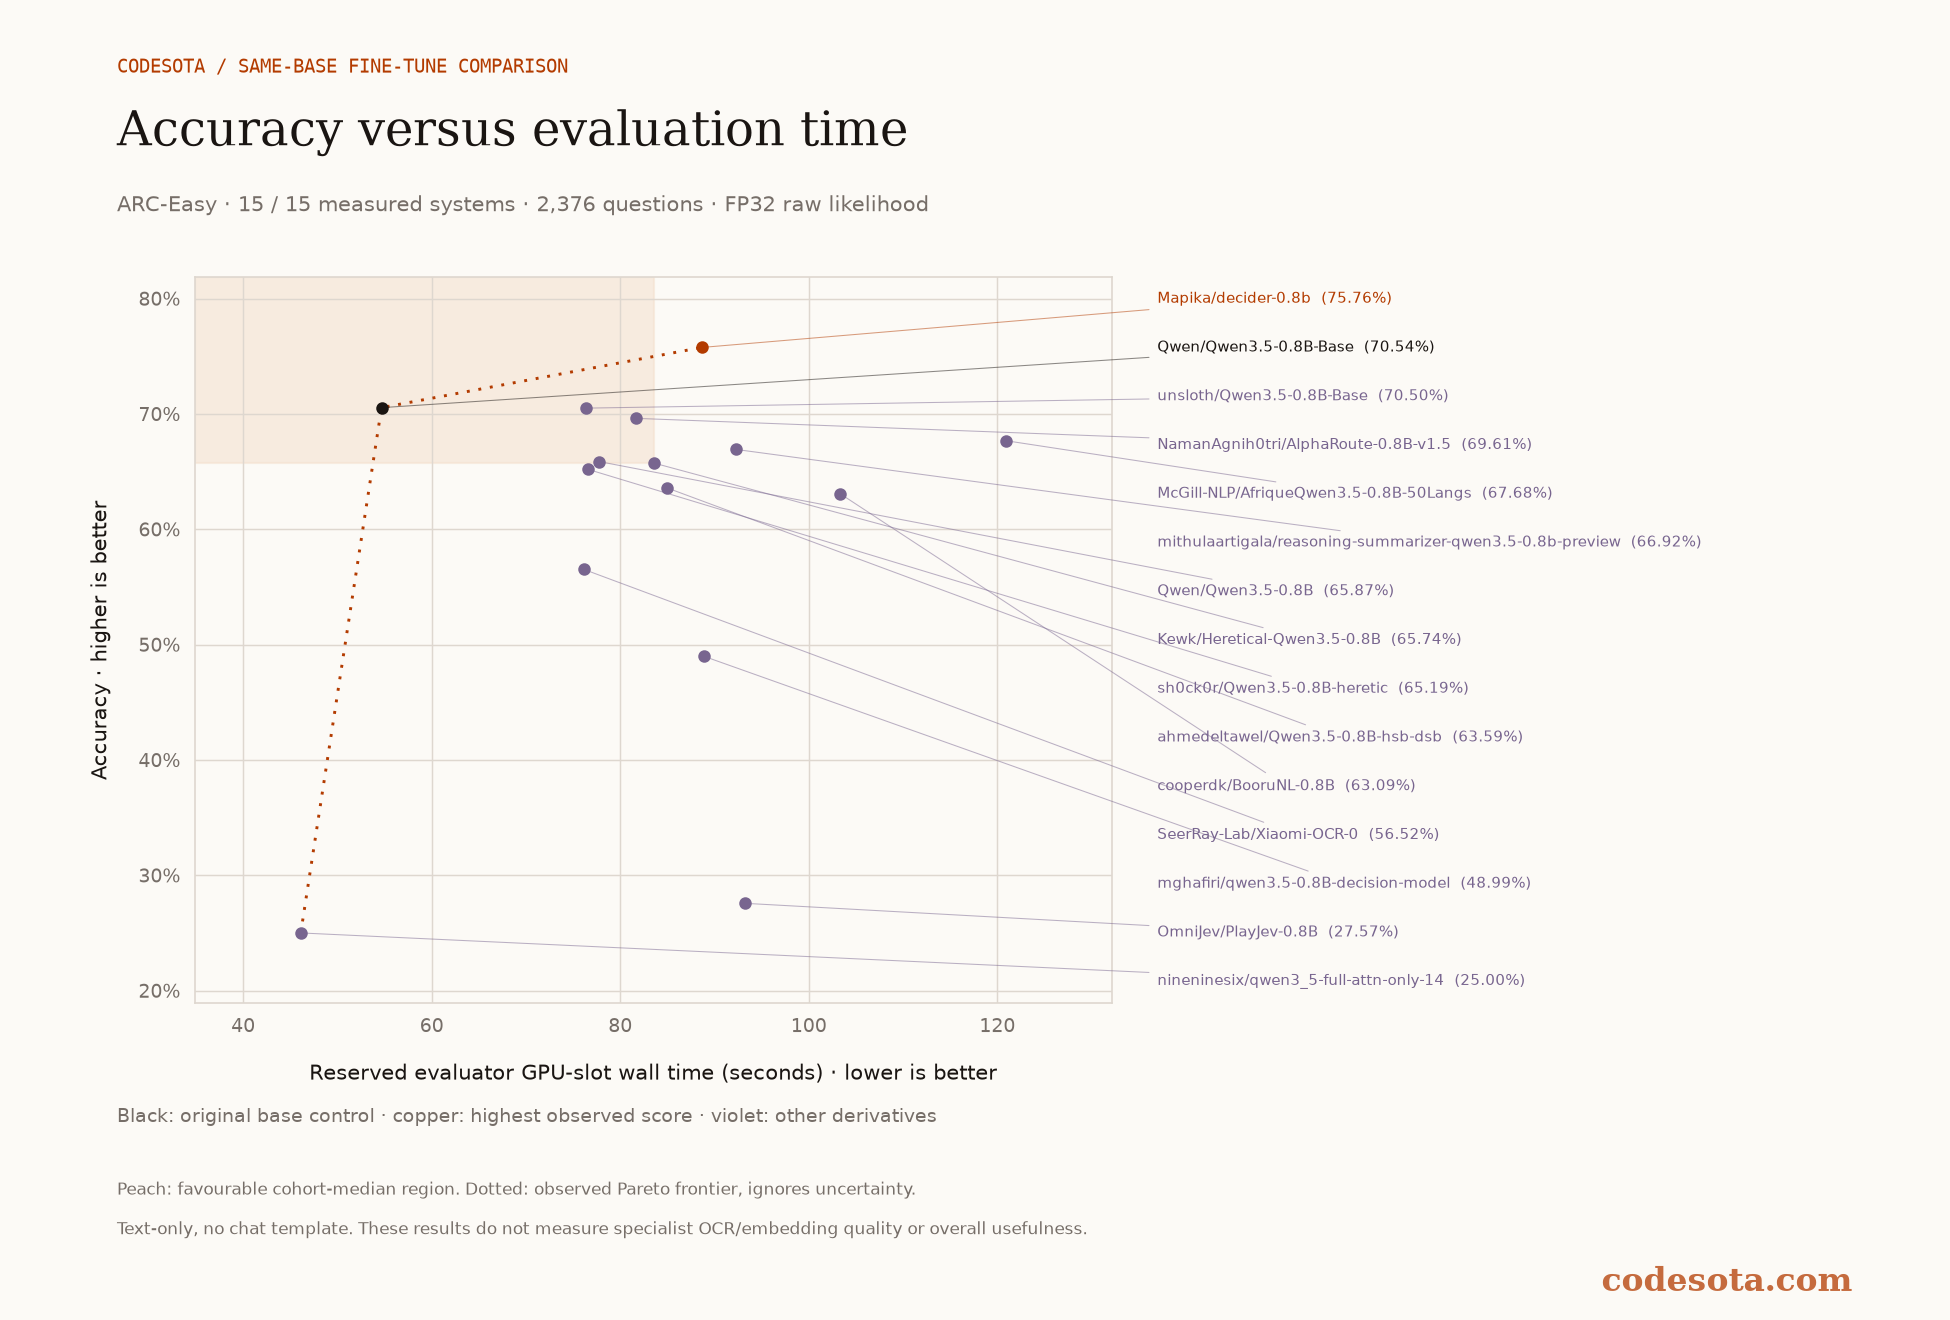
ARC-Easy
ARC-Challenge
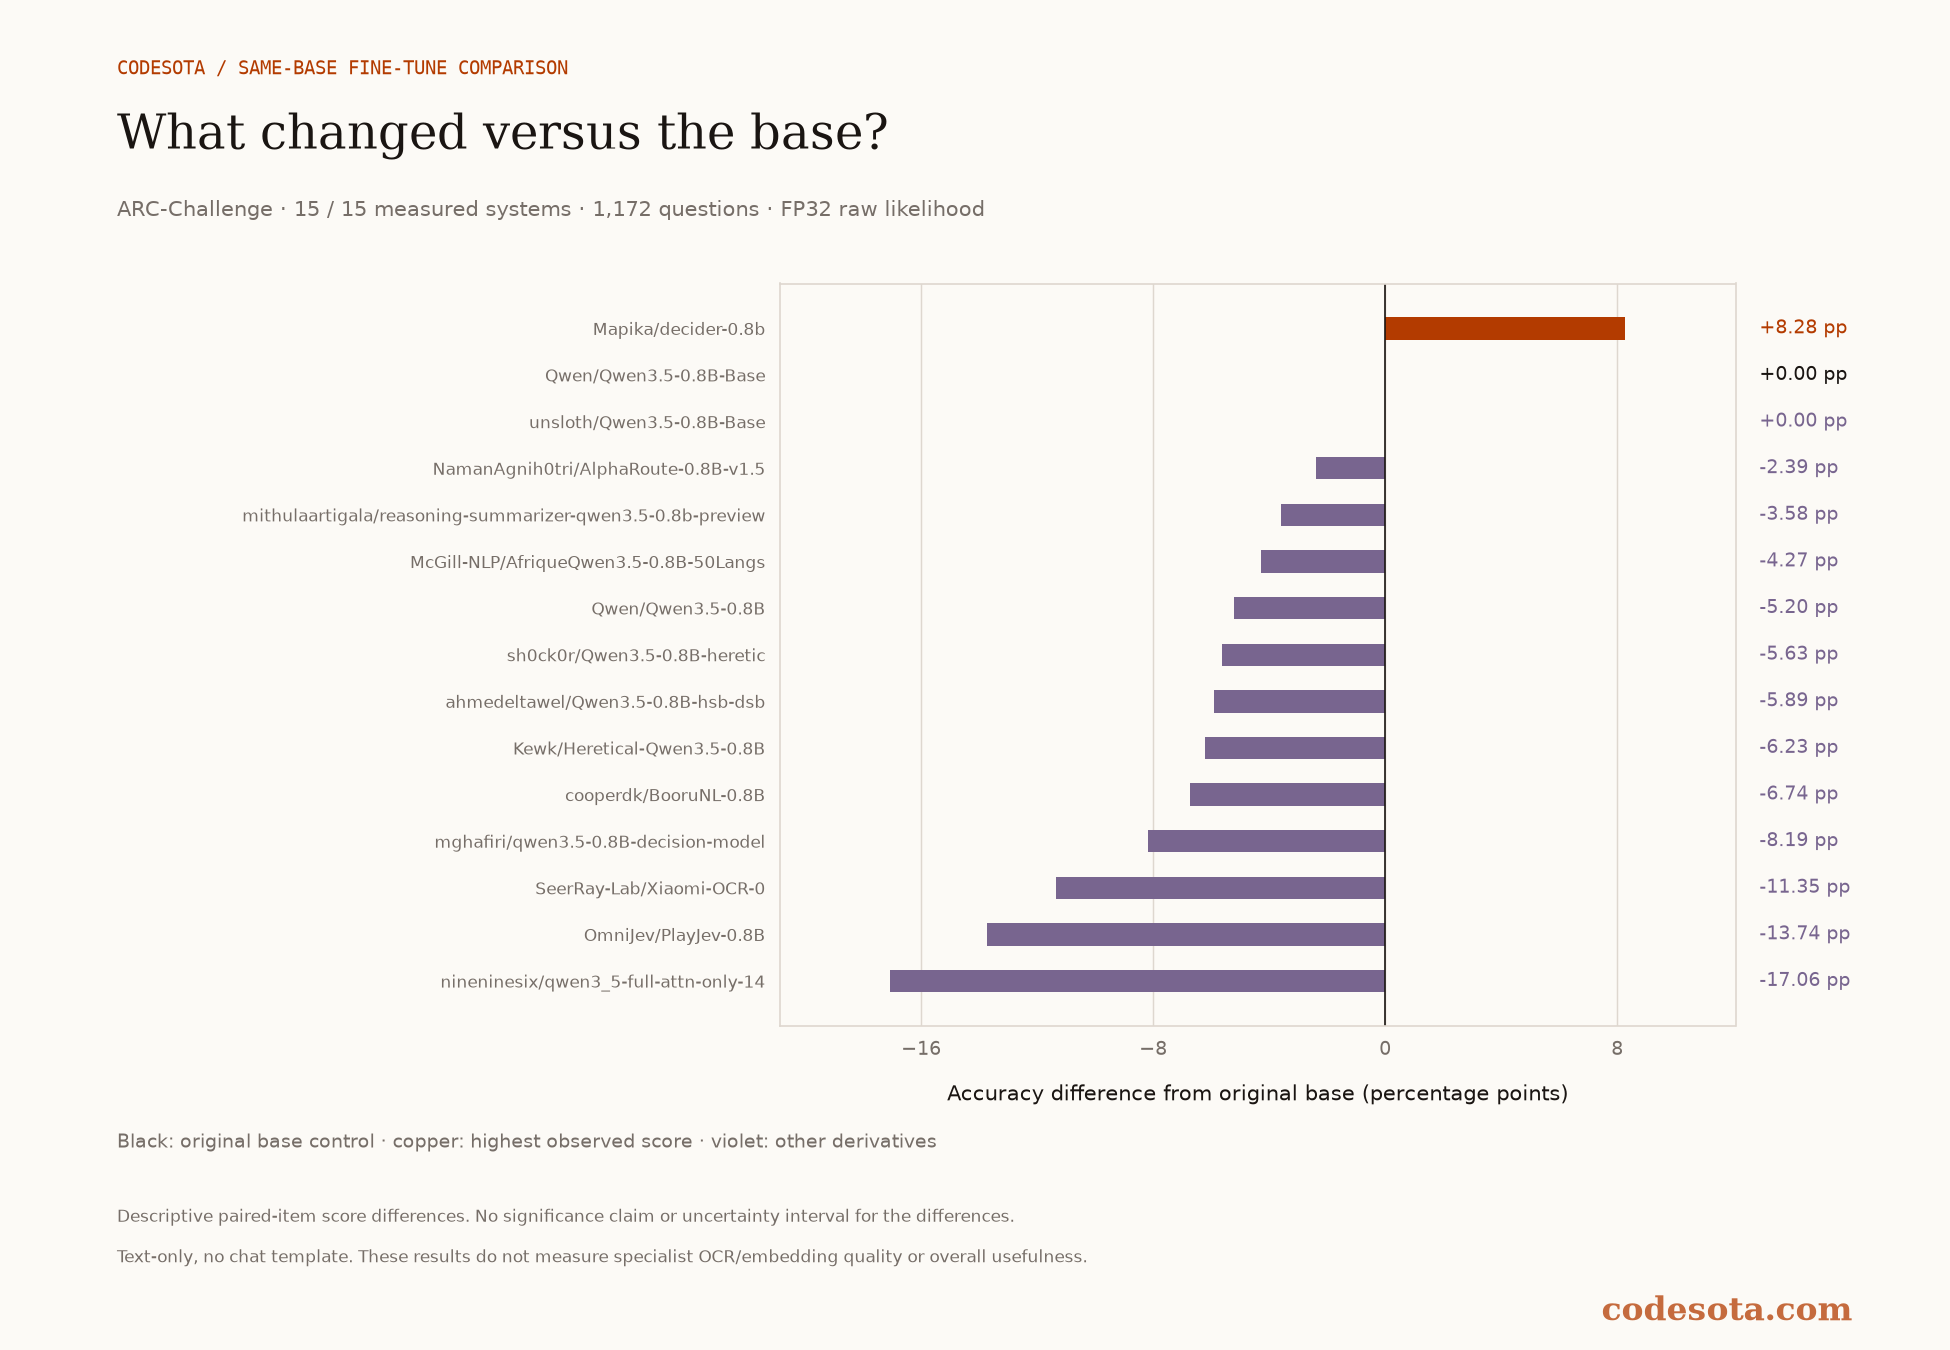
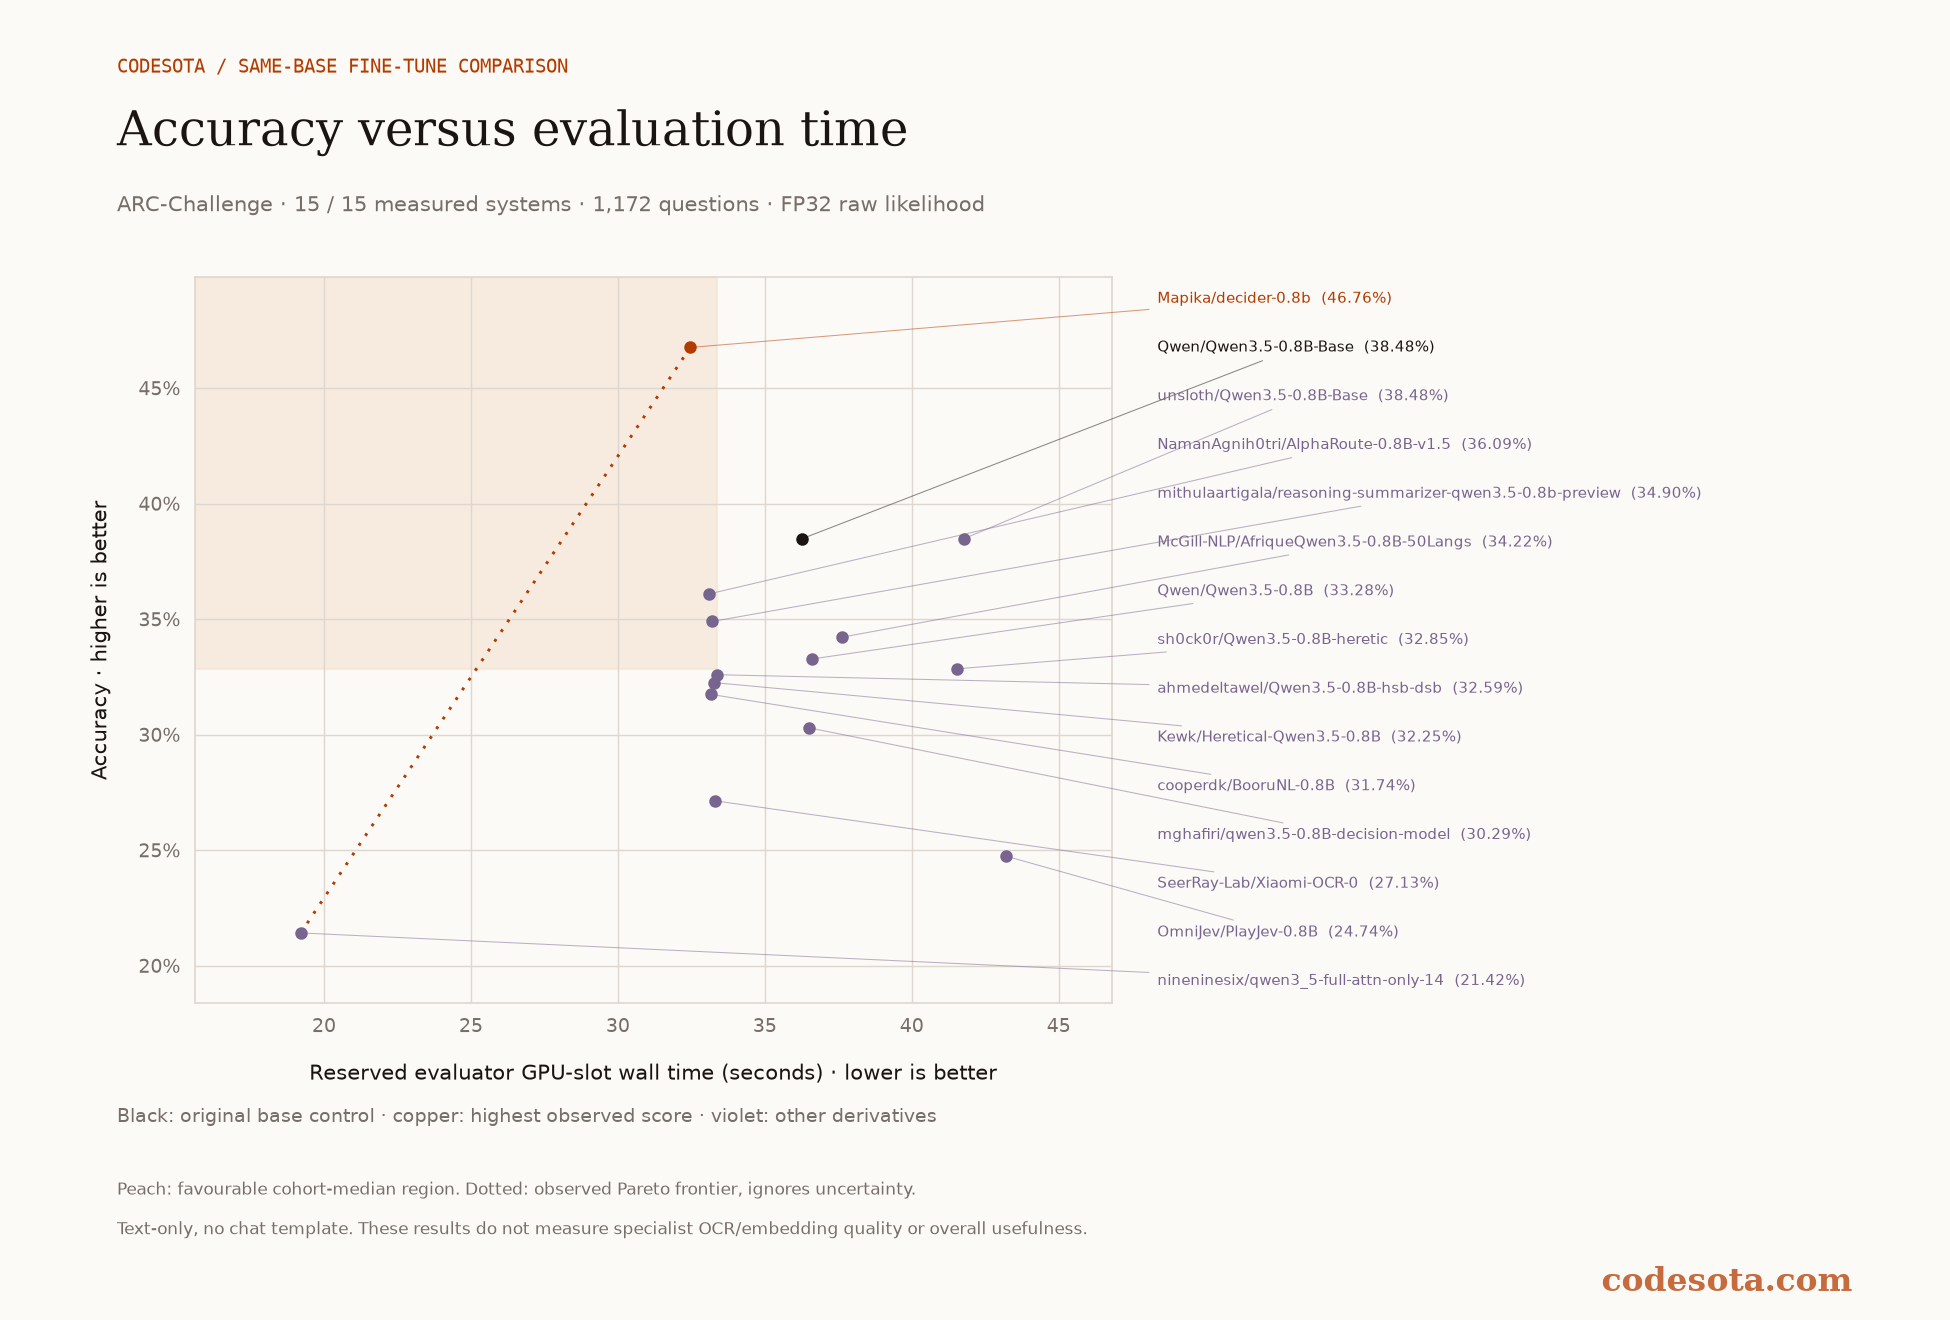
Comparison campaign · next stages
ARC-Easy is one diagnostic, not an overall winner. Follow-up tests use the same pinned systems and keep each protocol separate. Six selected repositories still require a different runtime or task protocol. Instruction following, coding, language coverage and specialist tasks remain unmeasured for this cohort.
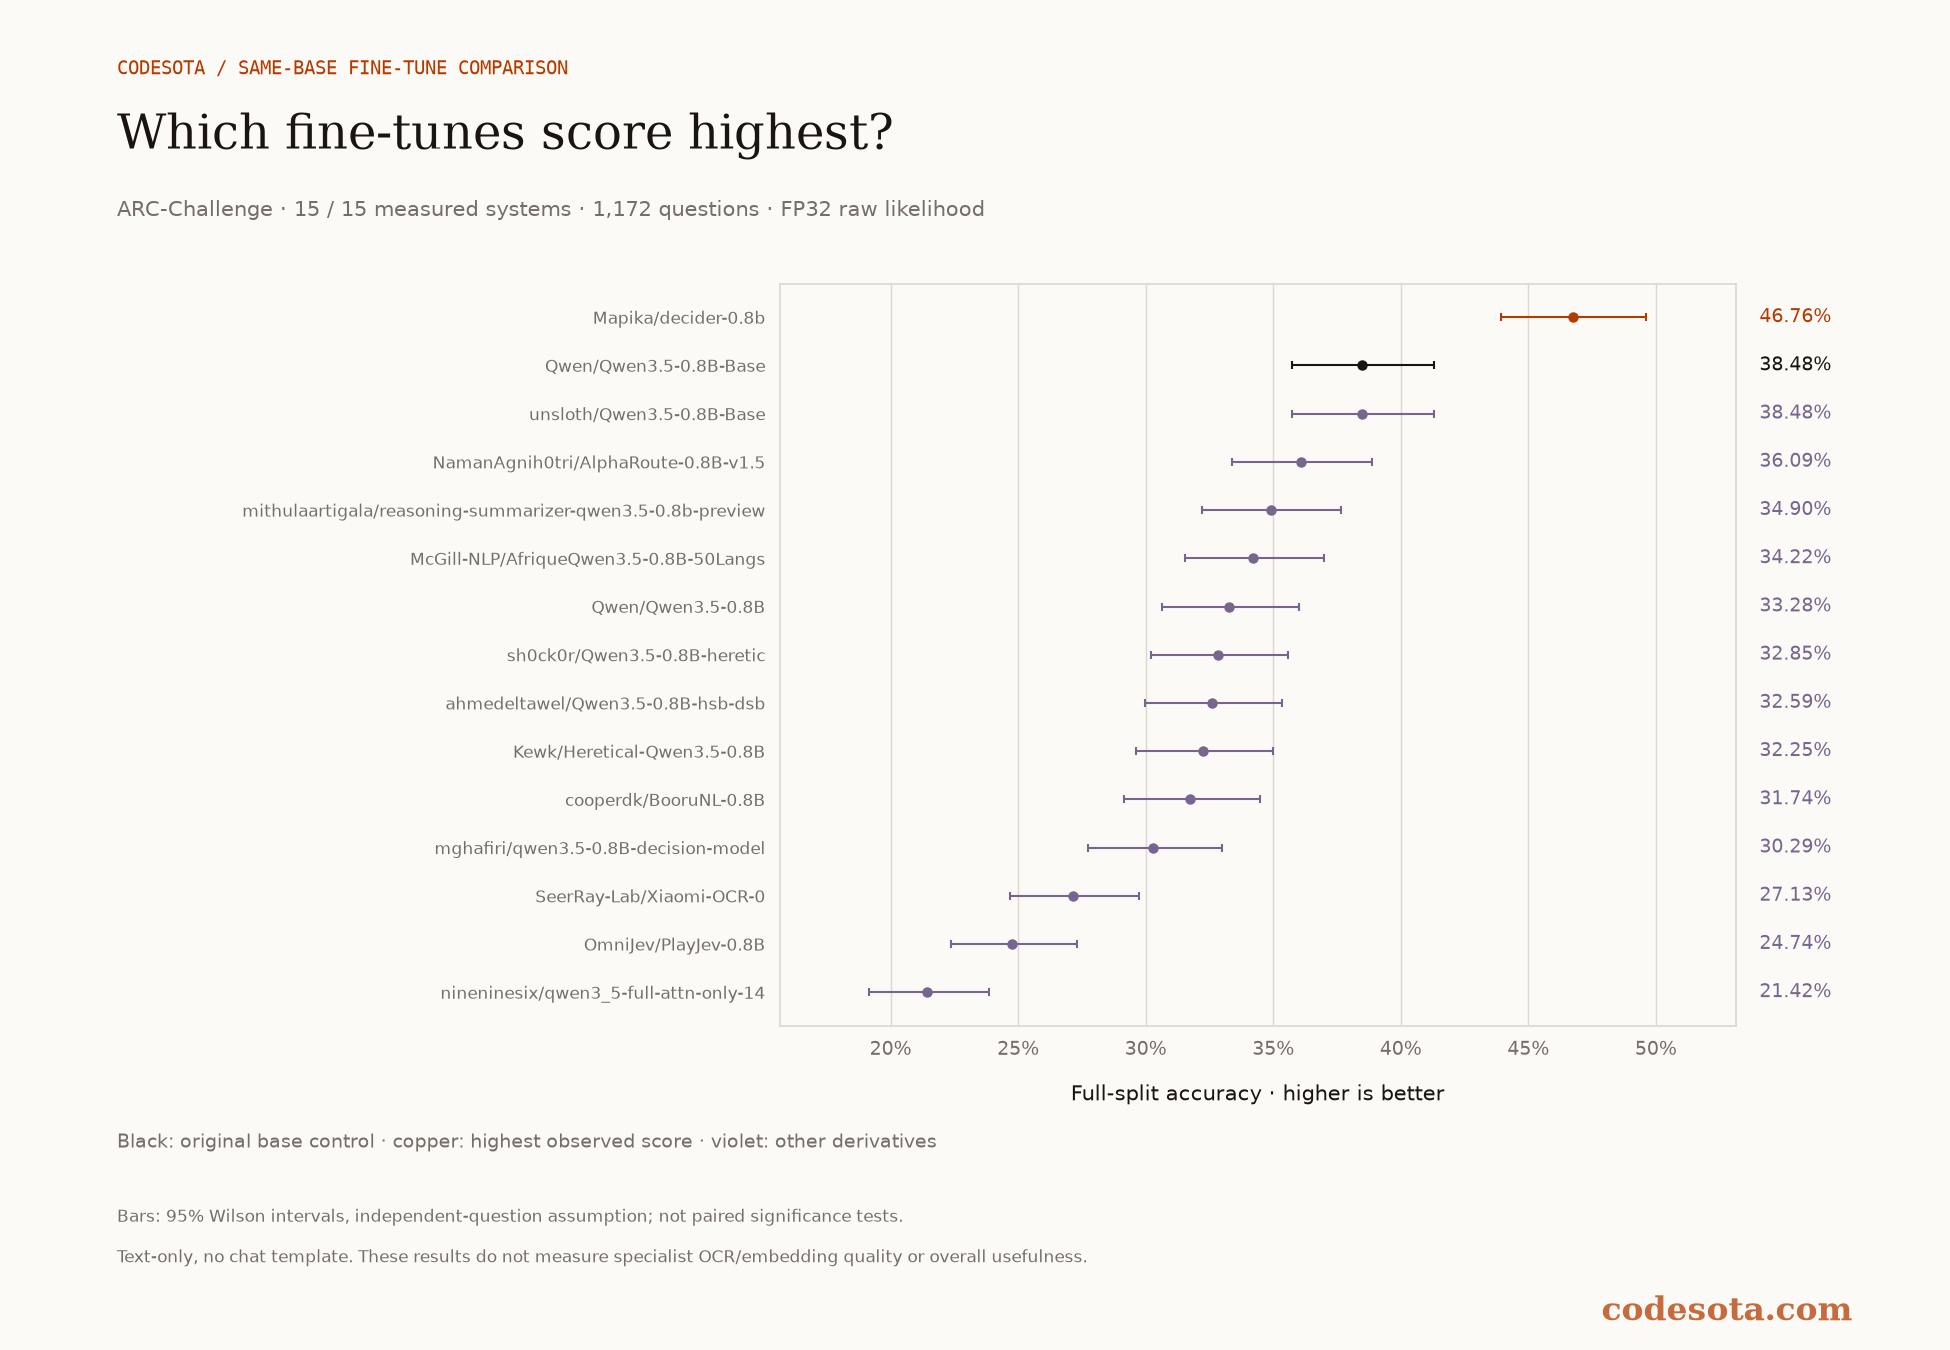
ARC-Challenge · full 1,172-question test
15 / 15 completed · 0 running · 0 queued
| System | Execution | Accuracy |
|---|---|---|
| Mapika/decider-0.8b | completed | 46.76% |
| Qwen/Qwen3.5-0.8B-Base | completed | 38.48% |
| unsloth/Qwen3.5-0.8B-Base | completed | 38.48% |
| NamanAgnih0tri/AlphaRoute-0.8B-v1.5 | completed | 36.09% |
| mithulaartigala/reasoning-summarizer-qwen3.5-0.8b-preview | completed | 34.90% |
| McGill-NLP/AfriqueQwen3.5-0.8B-50Langs | completed | 34.22% |
| Qwen/Qwen3.5-0.8B | completed | 33.28% |
| sh0ck0r/Qwen3.5-0.8B-heretic | completed | 32.85% |
| ahmedeltawel/Qwen3.5-0.8B-hsb-dsb | completed | 32.59% |
| Kewk/Heretical-Qwen3.5-0.8B | completed | 32.25% |
| cooperdk/BooruNL-0.8B | completed | 31.74% |
| mghafiri/qwen3.5-0.8B-decision-model | completed | 30.29% |
| SeerRay-Lab/Xiaomi-OCR-0 | completed | 27.13% |
| OmniJev/PlayJev-0.8B | completed | 24.74% |
| nineninesix/qwen3_5-full-attn-only-14 | completed | 21.42% |
Top 20 + original base control · ARC-Easy
21 of 21 selected systems displayed. Download ranks are frozen at selection time. Parameter totals are metadata, not loaded-model verification. Model-card claims remain separate from execution evidence.
| Download rank | Model / revision | Downloads | Declared task | Parameters / basis | Execution | ARC-Easy | Δ base |
|---|---|---|---|---|---|---|---|
| Base | Qwen/Qwen3.5-0.8B-Basedc7cdfe2ee41 | Control | base control | 853.0M Loaded unique parameter count | completed | 70.54% | +0.00 pp |
| 1 | Qwen/Qwen3.5-0.8B2fc06364715bCard: posttrained_general | 2,953,503 | image-text-to-text | 853.0M Loaded unique parameter count | completed | 65.87% | -4.67 pp |
| 2 | Mapika/decider-0.8ba0a01d6f8135Card: decision_specialist | 15,776 | text-classification | 752.4M Loaded unique parameter count | completed | 75.76% | +5.22 pp |
| 3 | iapp/OpenThai-SystemOnedc67b0295ab7Card: custom_decision_head | 11,505 | zero-shot-classification | 752.7M Below 1B in Hub metadata | different protocol required | — | — |
| 4 | SeerRay-Lab/Xiaomi-OCR-0ff990be318c4Card: ocr_specialist | 6,327 | image-text-to-text | 853.0M Loaded unique parameter count | completed | 56.52% | -14.02 pp |
| 5 | unsloth/Qwen3.5-0.8B-Base44bc982576bfCard: base_redistribution | 5,550 | image-text-to-text | 853.0M Loaded unique parameter count | completed | 70.50% | -0.04 pp |
| 6 | nineninesix/qwen3_5-full-attn-only-14a26dff91d90eCard: architecture_rebuild | 3,633 | unspecified | 511.2M Loaded unique parameter count | completed | 25.00% | -45.54 pp |
| 7 | OmniJev/PlayJev-0.8Ba7348002b1e1Card: game_decision_specialist | 1,322 | image-text-to-text | 853.0M Loaded unique parameter count | completed | 27.57% | -42.97 pp |
| 8 | mlx-community/Qwen3.5-0.8B-bf163067585164dbCard: mlx_conversion | 930 | image-text-to-text | 853.0M Below 1B in Hub metadata | different protocol required | — | — |
| 9 | djinn-san/QSIVba99bd489cf6Card: custom_decision_runtime | 810 | unspecified | 752.4M Below 1B in Hub metadata | different protocol required | — | — |
| 10 | FastFlowLM/Qwen3.5-0.8B-NPU204c06293f173Card: npu_conversion | 529 | image-text-to-text | Unknown Size requires verification | different protocol required | — | — |
| 11 | mithulaartigala/reasoning-summarizer-qwen3.5-0.8b-preview558fc651bf01Card: summarization_specialist | 466 | text-generation | 752.4M Loaded unique parameter count | completed | 66.92% | -3.62 pp |
| 12 | sh0ck0r/Qwen3.5-0.8B-hereticfb35b60374fcCard: abliterated_posttrained | 386 | image-text-to-text | 853.0M Loaded unique parameter count | completed | 65.19% | -5.35 pp |
| 13 | McGill-NLP/AfriqueQwen3.5-0.8B-50Langsf49099d79e51Card: multilingual_cpt | 363 | text-generation | 853.0M Loaded unique parameter count | completed | 67.68% | -2.86 pp |
| 14 | ahmedeltawel/Qwen3.5-0.8B-hsb-dsb7e781a3e9704Card: translation_specialist | 270 | text-generation | 752.4M Loaded unique parameter count | completed | 63.59% | -6.94 pp |
| 15 | kaptaan45/QaptaanLM-0.75Bd0055d68749dCard: custom_code_cpt | 224 | text-generation | 752.4M Below 1B in Hub metadata | needs adapter | — | — |
| 16 | Kewk/Heretical-Qwen3.5-0.8Bc16807de35d1Card: abliterated_posttrained | 192 | image-text-to-text | 853.0M Loaded unique parameter count | completed | 65.74% | -4.80 pp |
| 17 | cooperdk/BooruNL-0.8B14dbcf2e009fCard: tag_generation_specialist | 188 | text-generation | 853.0M Loaded unique parameter count | completed | 63.09% | -7.45 pp |
| 18 | Rebine/Etsu-Embedding-0.8B81ec0e2a88d6Card: embedding_specialist | 174 | feature-extraction | 752.4M Below 1B in Hub metadata | different protocol required | — | — |
| 19 | mghafiri/qwen3.5-0.8B-decision-model4a9939034a27Card: decision_specialist | 169 | text-classification | 752.4M Loaded unique parameter count | completed | 48.99% | -21.55 pp |
| 20 | NamanAgnih0tri/AlphaRoute-0.8B-v1.5ef87d71f1105Card: routing_json_specialist | 154 | text-generation | 752.4M Loaded unique parameter count | completed | 69.61% | -0.93 pp |
Rank measured results → · Cohort JSON → · Upstream catalogue ↗ · CodeSOTA ontology →
Protocols, tracks and ontology
One lineage, several tracks.
Text generation, OCR/vision and classification need separate task protocols. Format conversions and quantized copies should be grouped with their source checkpoint; changed architectures belong in a separate comparison. A declared base-model tag is evidence of lineage, not proof of identical architecture or training.
Compare gains, not just rank.
Report each benchmark score and its difference from the base control, paired uncertainty, regressions, throughput and GPU-slot time. With almost identical model sizes, score versus latency and per-task gain charts are more useful than a crowded parameter-size scatter plot. The first measurement is all 2,376 ARC-Easy test questions, raw summed answer likelihood, no chat template or images. This measures text capability of OCR/vision specialists, not their OCR quality. Charts will appear after compatible results exist.
Keep the evaluation controlled.
Pin model revisions and item IDs. Use a common completion protocol for base capability; evaluate chat-native behaviour separately with explicit templates, thinking settings and equal token budgets. Count reasoning tokens inside generation budgets. Full cheap tests can run directly; adaptive estimates for expensive tests need calibration and a distinct protocol, followed by fixed-set confirmation.
How it fits the ontology
A cohort groups pinned System versions by declared lineage. Tasks and Benchmarks define what is measured; Result links a System to a fixed Protocol. A card claim is reported evidence, not a CodeSOTA measurement.