Reasoning / CommonsenseQA (validation)
CommonsenseQA (validation)
Question + candidate answers → selected answer
Model size vs score
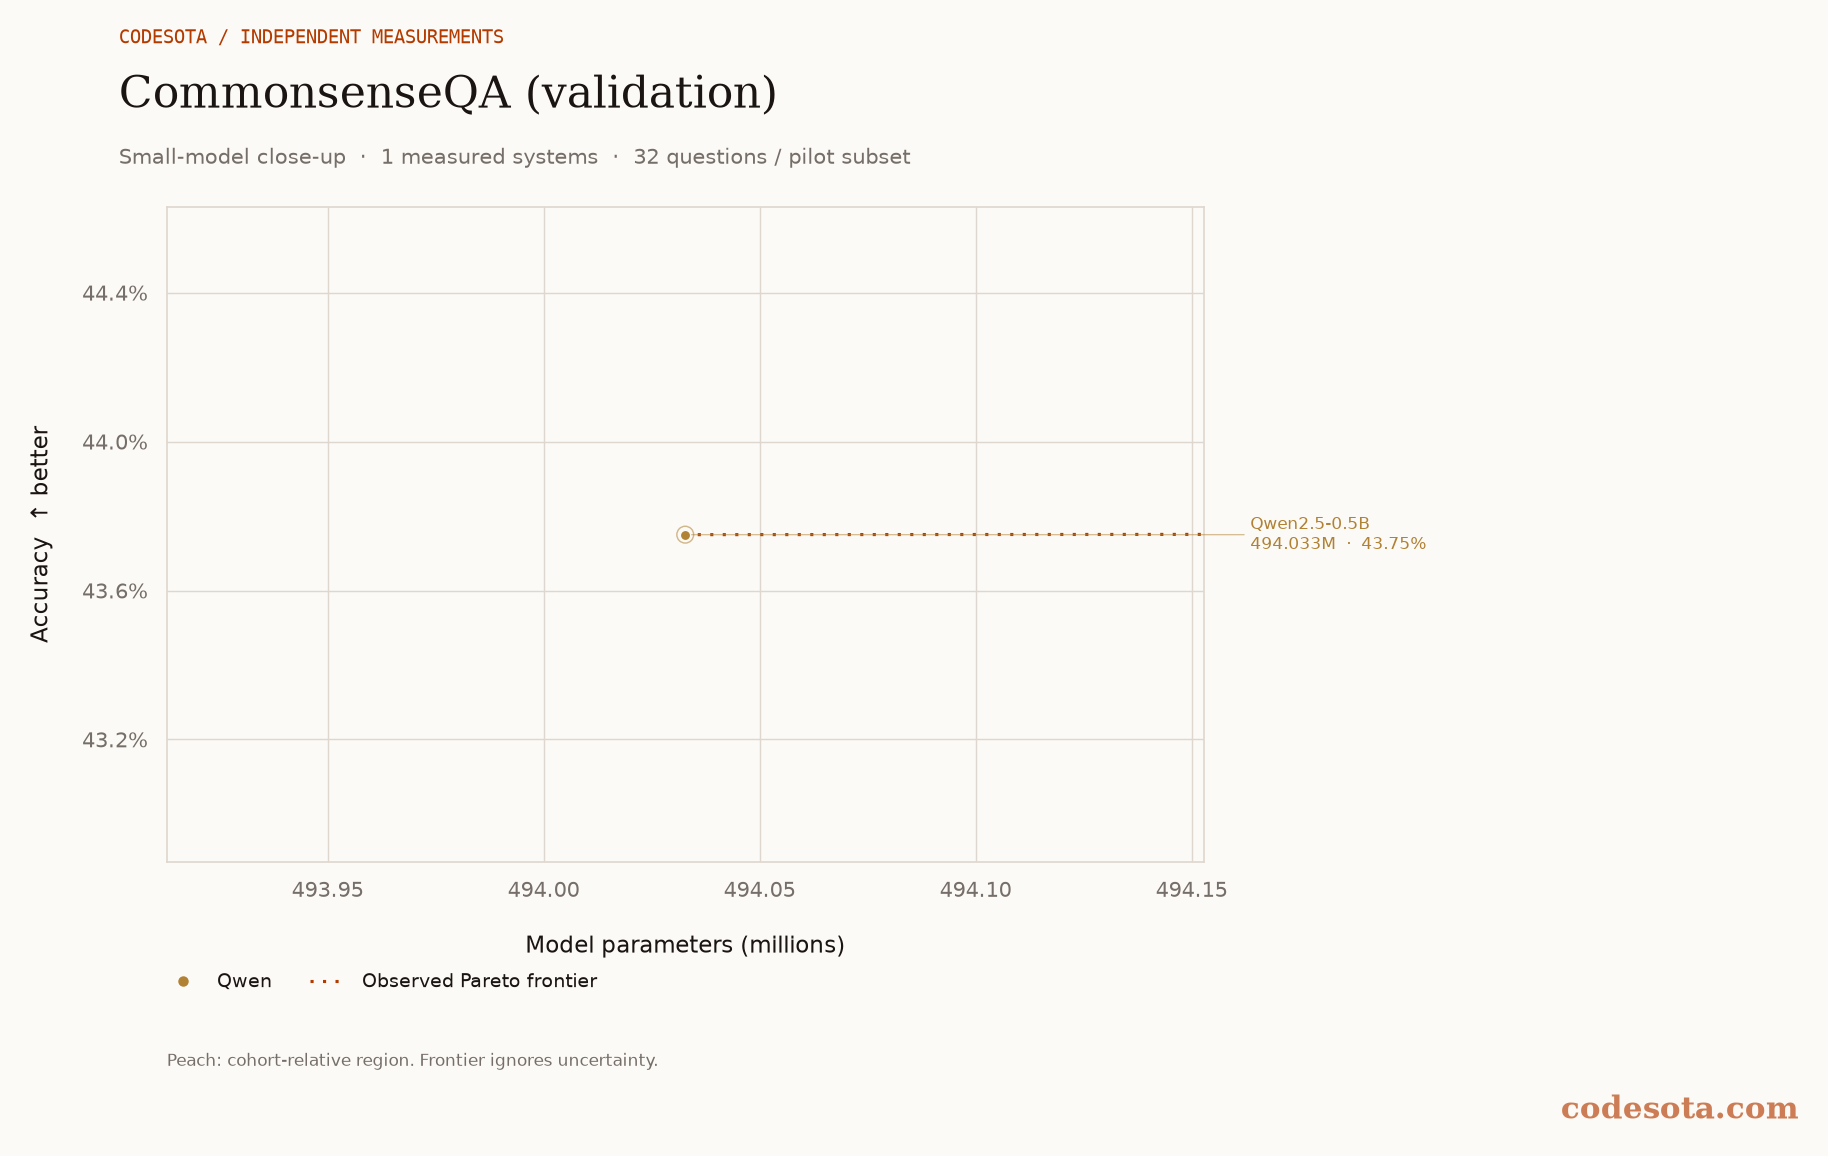
Static, watermarked figures. SlayerLab models are red. The close-up expands the crowded small-model cluster without changing any coordinates.
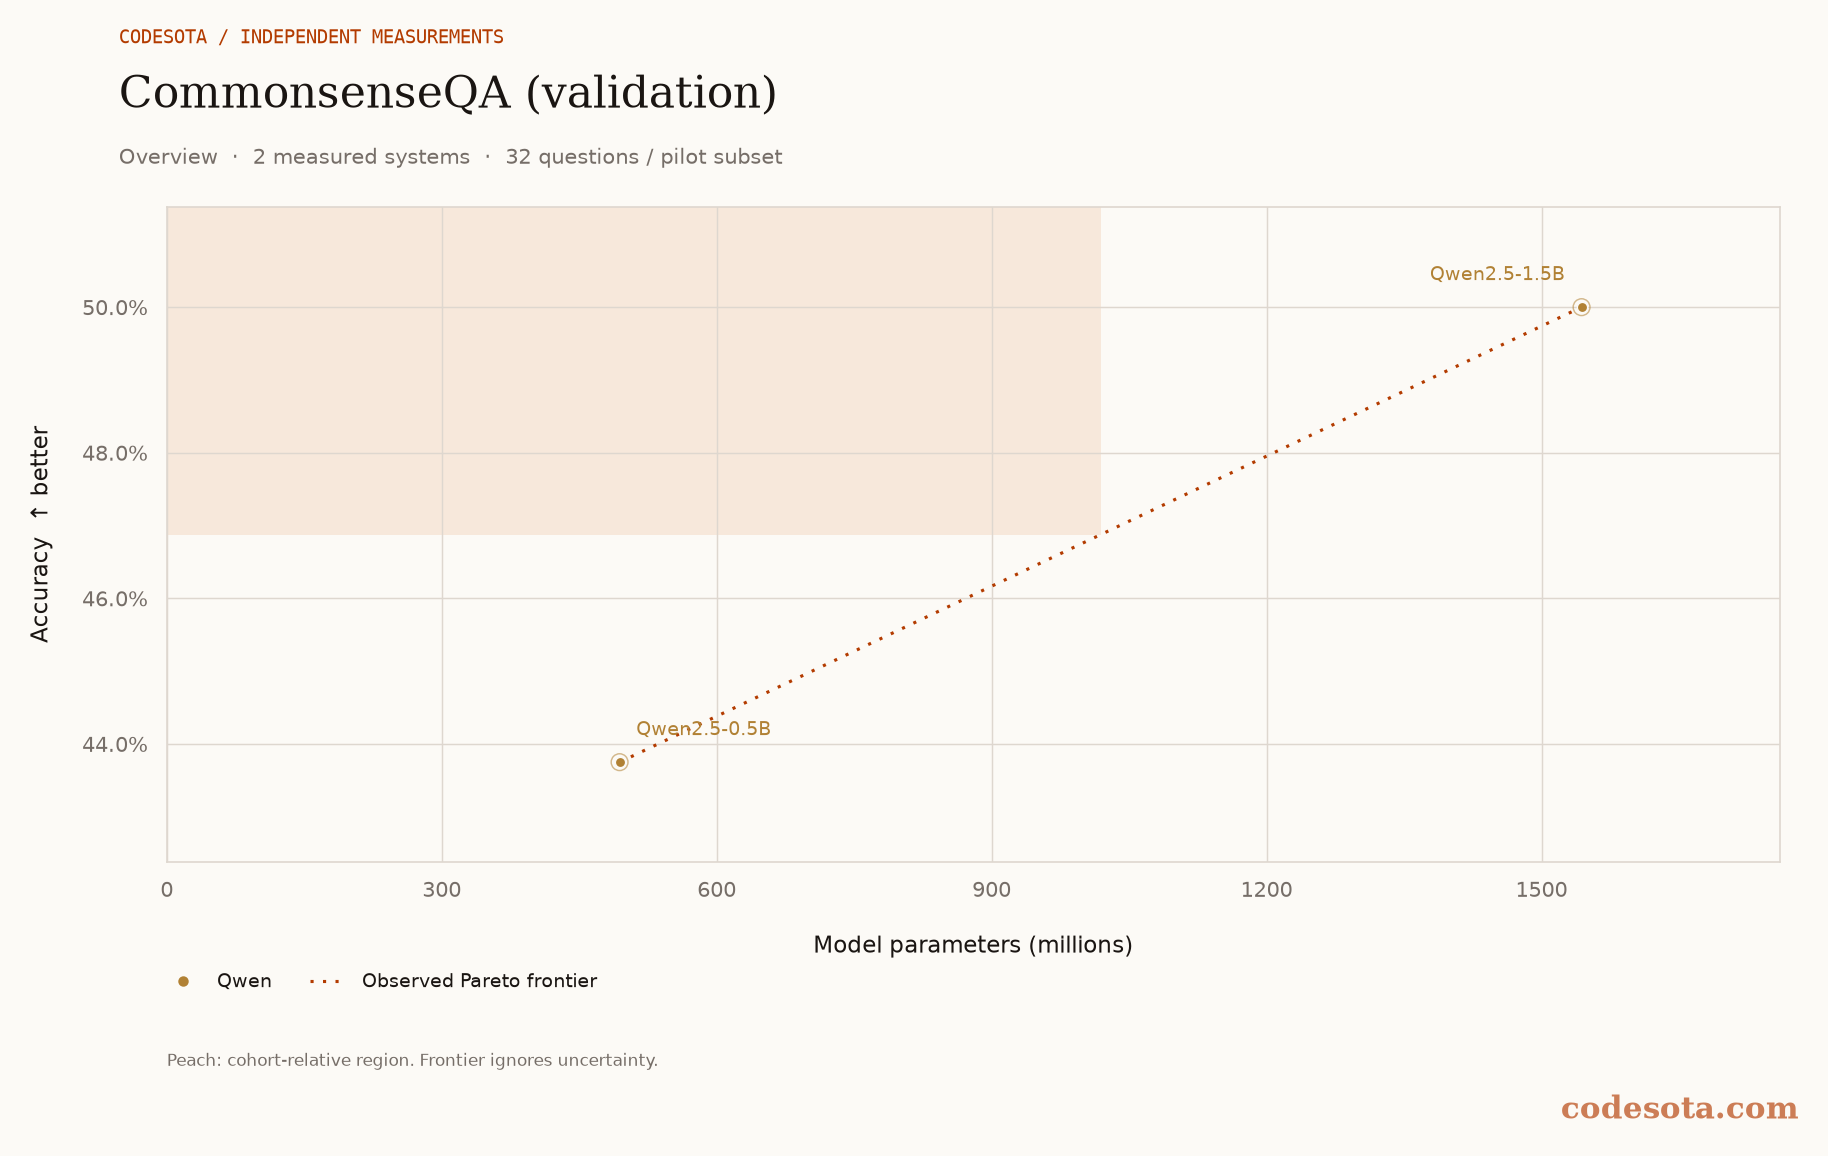
Measured results
Pilot comparison · 32 examples · accuracy higher is better. No global SOTA claim.
| System | Score | Samples | Elapsed¹ | Evidence |
|---|---|---|---|---|
| Qwen/Qwen2.5-1.5B 8faed761d45a | 50.0% | 32 | 2s | Inspect run → 17 Oct 2026, 15:37 UTC |
| Qwen/Qwen2.5-0.5B 060db6499f32 | 43.8% | 32 | 1s | Inspect run → 17 Oct 2026, 15:42 UTC |
¹ Evaluation elapsed time includes model loading after dataset selection. It is not serving latency or a fair speed comparison.
What this measures
Benchmark origin
Dataset / split
tau/commonsense_qa / validation
Immutable dataset revision
94630fe30dad47192a8546eb75f094926d47e155Upstream license metadata
mit · consult upstream terms
Protocol
codesota-choice-pilot-v2-batched / choice
Selection
First 32 valid examples in the pinned split order. SNLI rows without a valid label are excluded.
Configuration
Seed 42. Greedy generation for math and code. Mean answer-token log likelihood for text classification, completion and declarative multiple-choice recipes. No model judge.
Planned runs
0 qualified visits in 30 days · priority 6.6. Interest changes execution order, within the approved baseline list.
| System | Status |
|---|---|
| Qwen/Qwen2.5-1.5B | completed |
| Qwen/Qwen2.5-0.5B | completed |